-
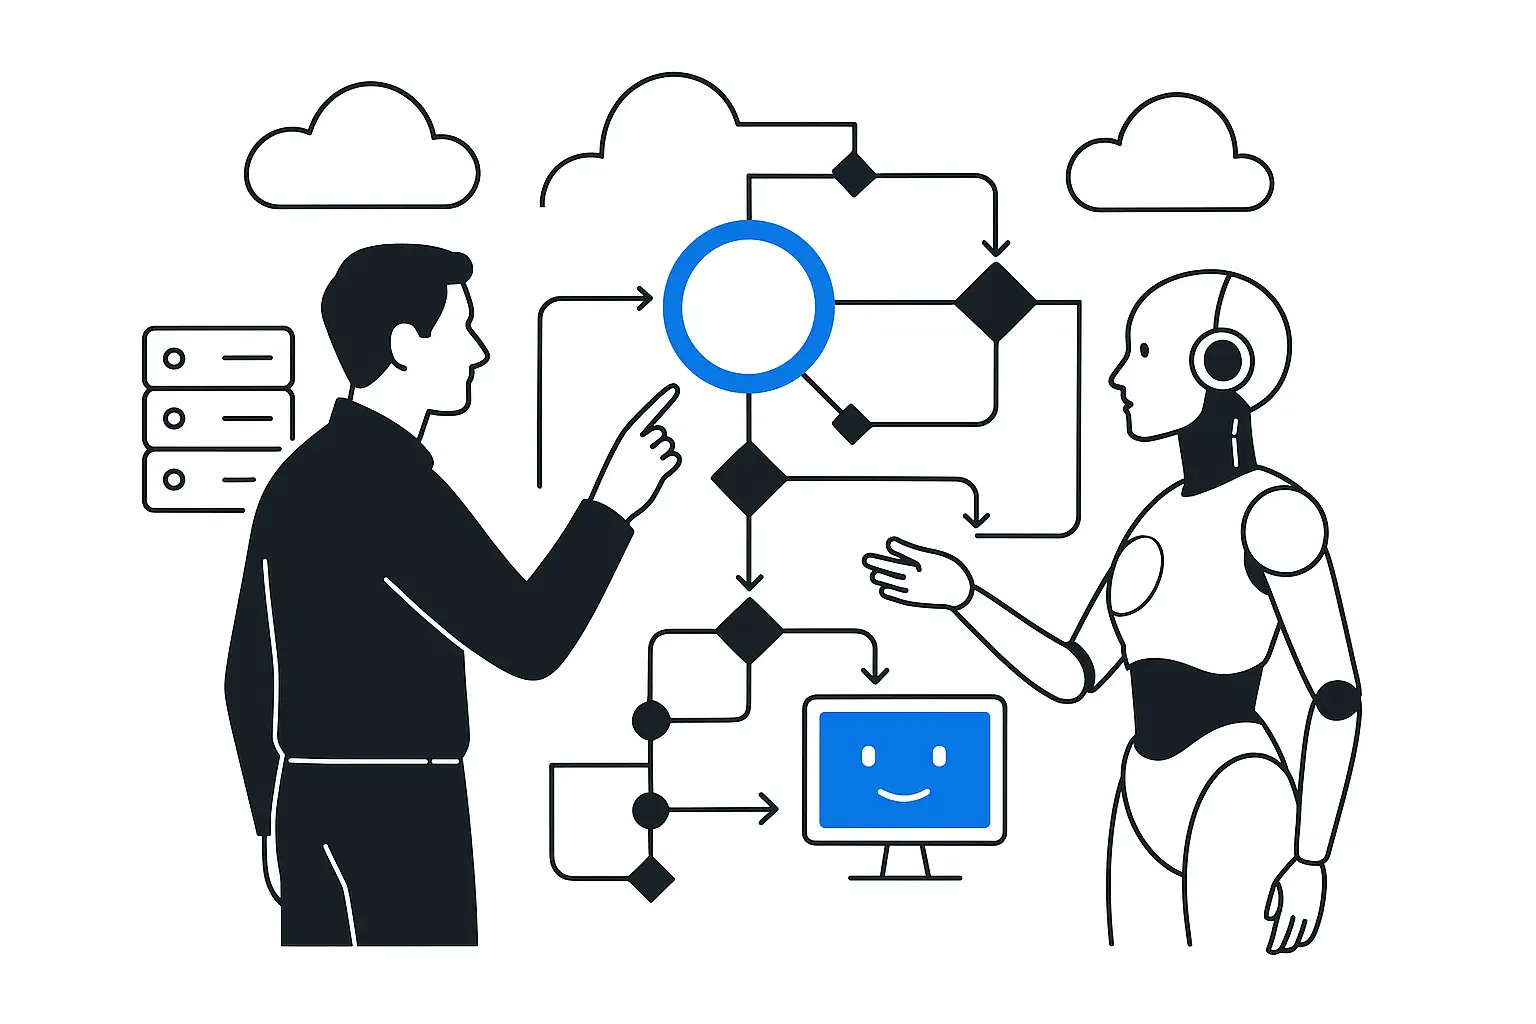
Architectural layers mitigate the risk, and choosing the “right” vendor guarantees nothing here. - A gateway in front of the models.
-
Applications access the LLM through a single gateway.
-
Changing the provider or model changes the gateway configuration, while the service code remains the same.
-
That is how our LLM & Security Gateway works: it also tracks requests and filters sensitive data. - The model version next to the vector. In a RAG system, each vector is stored with the model and version identifiers.
-
Recalculation can then run in batches in the background, and search does not stop. - Integrations through standard protocols.
-
Agent tools are published through MCP, while communication between systems runs through Apache Kafka.
-
The service runtime (Node.js, Python, or C#) can be replaced without revising contracts. - Open weights for large datasets.
-
For large embedding datasets, an open model with a clear license (Qwen, Llama, Gemma) costs less than relying on hosting that may be shut down.
-
This architecture may look dull, but its purpose is specific: if the vendor is acquired or raises prices next year, the move should take weeks of one team's work. We do not accept a quarter of work by several teams in this calculation.